Data Science Programmer · R and Oracle / Arrow
Moving data between systems
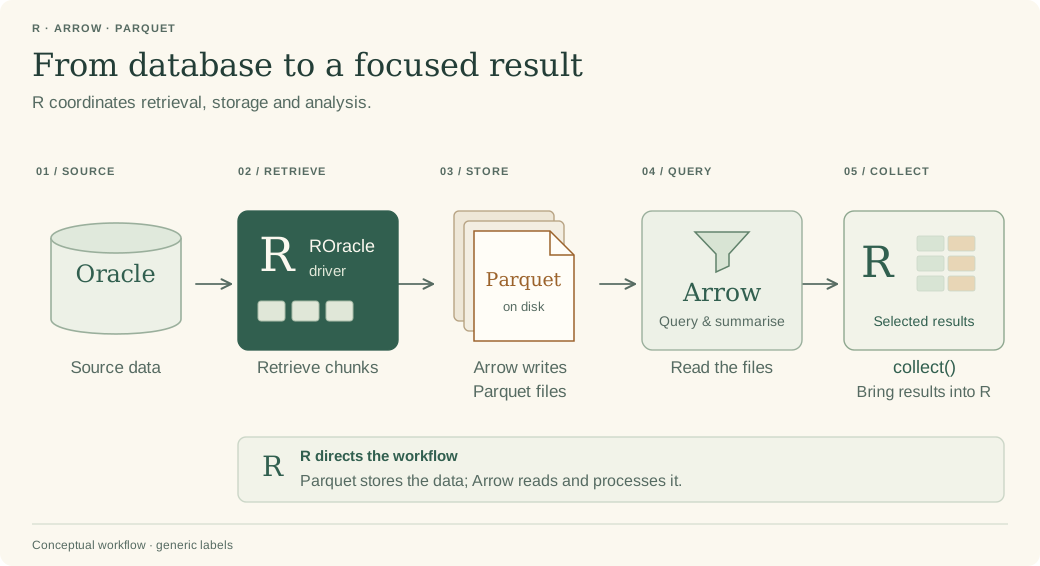
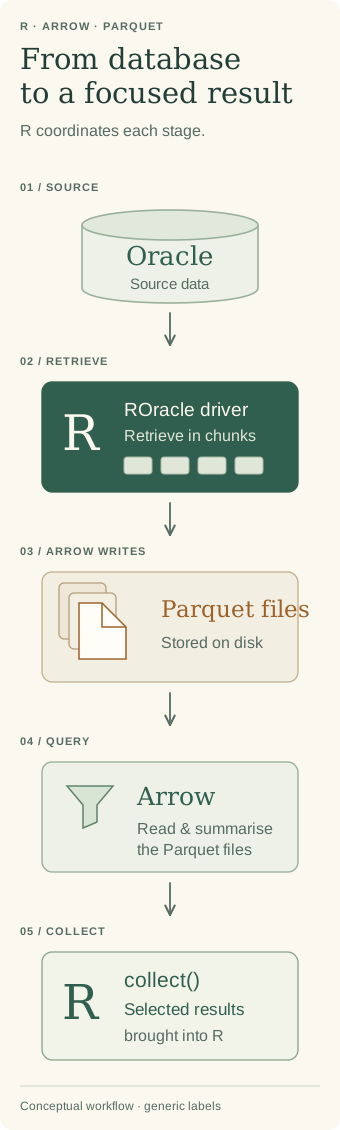
I compiled and installed the ROracle package from source, replacing the ODBC connection with much faster data access between R and Oracle. I then used Arrow and Parquet to work with larger datasets and bring selected results into R.
Selected historical code · Generic placeholders · No original data or saved outputs
From Oracle to selected R results
R directs the workflow: retrieve in chunks, store in Parquet, then use Arrow to query and collect the results needed for the next step.
01 / APPROACH
Retrieve through ROracle
Use the database driver to retrieve a selected query result and work with it in R.
R · adapted excerpt
driver <- dbDriver("Oracle")
# The connection is configured separately with this driver.
query <- dbSendQuery(connection, query_text)
chunk <- fetch(query) %>% as_tibble()
dbDisconnect(connection)
Connection setup and the query are omitted or represented by placeholders, and no results are shown. This retrieves one chunk; how chunks are selected is omitted.
02 / APPROACH
Store chunks, collect a summary
Write each chunk to Parquet, then query the dataset and collect the smaller result.
R · adapted excerpt
write_parquet(chunk, compression = "zstd", sink = output_file)

dataset <- open_dataset(dataset_dir)
summary <- dataset %>%
  group_by(group_a, group_b) %>%
  summarise(mean_value = mean(value)) %>%
  ungroup() %>%
  collect()
Generic object and field names stand in for the original data. Chunk selection and file setup are omitted.